Big ideas · from the full text
Attention Is All You Need
by Ashish Vaswani et al. · 3 min read · Lumina’s commentary, written with AI
About this paper
The 2017 paper from eight Google researchers that introduced the transformer: a model that reads a whole sentence at once and learns which words to pay attention to, instead of plodding through it one word at a time. Every large language model since, including the GPT family, is built on it. Free to read on arXiv at arxiv.org/abs/1706.03762.
♫ AI-generated voice · press play below to listen and read along; tap any passage to jump to it
Attention becomes the center of the model
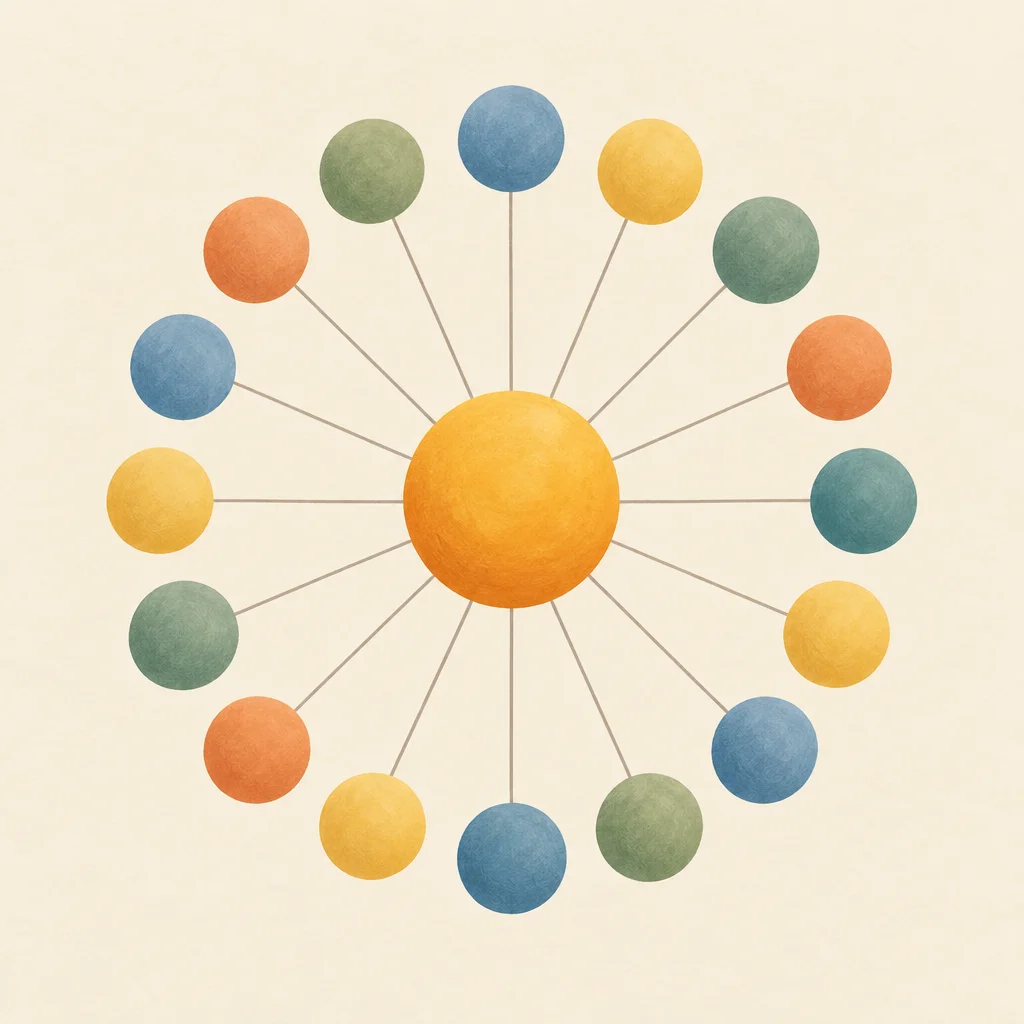
In Attention Is All You Need by Ashish Vaswani et al., the Transformer puts attention at the core of sequence modeling. Each position forms a query, compares it to keys at other positions, and mixes the corresponding values using the attention scores. This shifts the main sequence computation away from recurrent or convolutional layers, while keeping an encoder–decoder layout for translation. In the decoder, attention is used both within earlier outputs and over encoder outputs.
Why it matters
This change lets the model connect distant positions directly and allows more work to run in parallel during training.
An example
The decoder uses masked self-attention over earlier output positions and attention over encoder outputs.
Keep in mind
The decoder still creates the target sequence one token at a time.
The design must add order and separate attention patterns
In Attention Is All You Need by Ashish Vaswani et al., attention alone does not encode word order the way recurrence does. The design adds position information to token embeddings using sine-and-cosine signals. It also uses multiple attention heads, each with its own learned projections, so the model can represent more than one relationship pattern instead of compressing all links into a single attention map. Reported tests compare learned position embeddings with fixed sinusoidal ones.
Why it matters
The main idea works because the model also handles problems that attention creates.
An example
In the reported tests, learned position embeddings perform almost the same as fixed sinusoidal ones.
Keep in mind
The paper gives extrapolation as a reason for sinusoidal encodings, but the summary does not show a proven advantage in those results.
Parallel training helps, but the cost does not vanish
In Attention Is All You Need by Ashish Vaswani et al., self-attention is presented as reducing forced step-by-step computation: many positions can interact in a small number of sequential operations. This supports more parallel work during training and keeps the path between distant positions short. However, the paper also treats very long sequences as challenging for attention. It discusses restricting attention to local neighborhoods for very long inputs, which changes how distant connections are handled.
Why it matters
Readers should not turn the efficiency claim into a rule for every sequence length or task.
An example
According to the summary, self-attention runs faster than a recurrent layer whenever the sequence is shorter than the representation size.
Keep in mind
For very long inputs, the paper discusses limiting attention to local areas, which would lengthen distant paths.
The experiments support the claim within a clear scope
In Attention Is All You Need by Ashish Vaswani et al., the paper reports machine translation scores, estimated training cost comparisons, tests of design choices, and a parsing experiment. Together, these results support the claim that attention can organize a strong sequence model in the settings tested. But they do not establish the same gains for every data type, every sequence length, or every future context. The summary also notes an internal inconsistency in reported English–French BLEU values.
Why it matters
The lesson is more useful when treated as a supported design result, not as a universal law.
An example
A four-layer Transformer is tried on English constituency parsing with little task-specific adjustment.
Keep in mind
The supplied summary reports two different English–French BLEU values in different parts of the paper.
Who's talking about Attention Is All You Need
Public statements we checked against the original source
- Discussed it
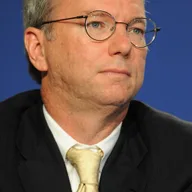 Eric SchmidtFormer CEO of Google
“a famous Google paper in 2017 called Attention is All You Need”
Transcript: US Lawmakers Probe AI's Role in Energy and Climate ↗TechPolicy.Press
Portraits from Wikimedia Commons · photo credits and licences